New Relic has introduced AI Evaluation, a new capability within New Relic AI Observability designed to help enterprises monitor the quality, behavior, and guardrail performance of generative AI applications in real time. The company also added an integrated AI experimentation environment with run history, dataset versioning, side-by-side prompt testing, and regression testing to help developers evaluate and improve AI applications before deployment.
In the AI era, an application can be highly available and responsive while still producing inaccurate, unsafe, or low-quality responses. Traditional monitoring tools often struggle to detect silent semantic failures associated with AI applications, such as factual hallucinations, personally identifiable information (PII) leaks, or malicious prompt injections. Historically, engineering and security teams have relied on manual log reviews to catch these semantic failures.
Built into the New Relic platform, AI Evaluation utilizes an asynchronous “LLM-as-a-judge” service to evaluate sampled live telemetry, grading prompt inputs and completions against predefined parameters. Connecting this evaluation data with application traces creates a powerful flywheel, giving organizations a better understanding of AI application health rather than relying on isolated data silos.
“Generative AI has redefined application health, making evaluation of response quality and model efficiency just as critical as uptime,” said New Relic Chief Product Officer Brian Emerson. “With AI Evaluation, we are bridging the fundamental trust gap for enterprise AI. By pairing real-time qualitative guardrail checks with deep trace telemetry, teams can better protect customer trust, prevent data leaks, and optimize infrastructure costs. Engineering, security, and product leaders gain the data and confidence required to move GenAI applications from pilot to high-impact production.”
Key features and benefits of the new capabilities include:
Real-Time AI Evaluation and Guardrails:
-
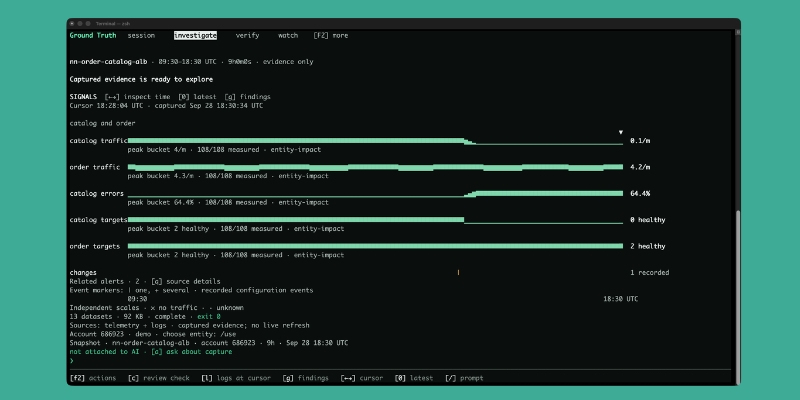
Direct Trace Integration for Rapid Troubleshooting: AI Evaluation attaches probabilistic quality scores to core deterministic distributed traces. Instead of chasing bad answers through siloed logs, engineers can view the prompt payload, judge reasoning, and cross-stack application behavior in a single screen to instantly isolate and resolve issues.
-
Automated Guardrail Checks: Configurable guardrails evaluate sampled inputs and outputs to help spot malicious prompt injections, jailbreak attempts, and accidental PII leaks, toxicity, and bias so that engineering teams can take action before these issues cause reputational damage, regulatory fines, or other issues.
-
RAG Architecture Efficacy: By helping to measure metrics like faithfulness and answer relevancy, engineers can separate a model’s reasoning performance from a vector database’s retrieval logic to help determine exactly why a response failed to meet its standards.
-
Connecting AI Quality to Compute Cost: AI Evaluation helps operators identify when models are underperforming qualitatively relative to their token cost, enabling teams to switch to better performing and affordable models without sacrificing the end-user experience.
-
Out-of-the-box Evaluators: Pre-built evaluators simplify the configuration process for users.
Experimental Environment for Rigorous Evaluations Pre-Production:
-
Prompt Playground: Engineers can test and refine prompts against real models side-by-side in a secure environment before deployment.
-
Reusable Datasets: Teams can easily curate and version “golden datasets,” sourced either from their real distributed traces or synthetic data, to run reliable regression tests on any changes.
- Prompt Tracking & Controlled Experiments: Organizations can run controlled A/B testing across different prompts, models, and configurations, reducing the guesswork of prompt engineering.
“As organizations move generative AI applications from early pilots into mission-critical production environments, traditional application performance metrics are no longer sufficient on their own,” said Stephen Elliot, Group Vice President, I&O, Cloud Operations, and DevOps at IDC. “A successful AI implementation requires visibility into both technical health and response quality, including accuracy, safety, and model efficiency. Bridging live response evaluation with prompt lifecycle management and full-stack operational telemetry is becoming essential for enterprise engineering and security teams looking to mitigate risk and manage costs effectively.”
Learn More at https://newrelic.com/
New Relic Now October 2026 Round-up
Related News:
New Relic Launches Infrastructure 360 to Accelerate Incident Response
SailPoint Report Reveals Major Identity Security Gap for AI Agents