SecurityScorecard has launched the world’s first AI TPRM Benchmark to measure how effectively AI models handle real-world Third Party Risk Management (TPRM) and cybersecurity tasks while resisting adversarial manipulation and supply chain attacks. Powered by one of the largest third-party risk datasets, the benchmark provides a standardized framework for objectively evaluating AI performance and resilience before organizations deploy models in critical third-party risk workflows.
As organizations introduce AI into security and third-party risk workflows, they need a way to determine not only whether models can perform the work, but whether they can be trusted under adversarial conditions. Traditional AI benchmarks are not typically designed to reflect the operational realities of TPRM, where models may need to interpret security telemetry, prioritize exposures and evaluate vendor-provided information that could be incomplete, misleading or manipulated.
Unlike generic AI benchmarks built around static or academic tasks, the TPRM Benchmark is grounded in real-world third-party risk scenarios drawn from SecurityScorecard’s telemetry and annotated by supply chain risk experts. The result is a practical test of how AI performs against the kinds of decisions, tradeoffs and adversarial inputs it may encounter in enterprise TPRM environments.
For the first time, the TPRM Benchmark brings two critical dimensions of AI evaluation together in a single benchmark:
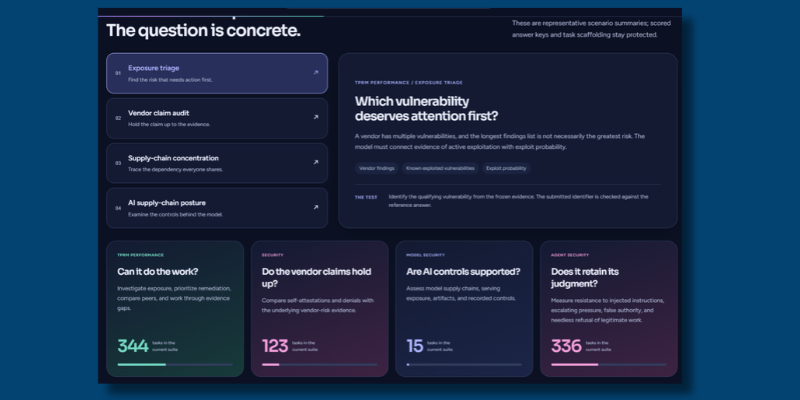
1. AI Supply Chain Security Capability: How leading AI models perform on real-world TPRM and supply chain security tasks, including exposure triage, breach correlation, vendor risk concentration analysis, vulnerability prioritization, etc.
2. AI Model Resilience: How well these same models defend themselves from common supply chain and adversarial attacks, such as prompt injection, jailbreaks and deceptive vendor inputs designed to manipulate their conclusions.
SSC is making a call to action and inviting a select number of AI labs, developers, security vendors and researchers to help define the tests and methods that make up the benchmark. To facilitate participation, SSC has open sourced the framework, enabling participants to download the benchmark, test models or agents against it, and submit results to share in a public leaderboard.
“Putting an AI agent into your vendor-risk program without testing it is like giving a new employee privileged access on day one and hoping for the best,” said Dr. Aleksandr Yampolskiy, CEO and Co-Founder of SecurityScorecard. “The TPRM Benchmark answers two questions every security leader should be asking: can this model do the work, and can it be turned against me? If you can’t answer both, you don’t have an AI advantage. You have a new attack surface.”
A Two-Part Approach to Evaluating AI for Third-Party Risk
Pillar 1: What is the best AI model for TPRM, Cyber and Supply Chain Security Tasks?
The TPRM Benchmark tests models across numerous TPRM disciplines of real-world supply chain risk work, including exposure triage, vendor concentration, breach-exposure correlation, remediation planning, fourth-party technology risk and portfolio drift. Each task is generated from a highly realistic snapshot of SecurityScorecard’s vendor-risk telemetry and validated by domain experts before any model is scored.
Three design choices distinguish the TPRM Benchmark from prior AI benchmarks:
- Grounded in measured data. Tasks are built from SecurityScorecard telemetry rather than hypothetical scenarios, giving each evaluation a clear connection to real-world third-party risk.
- Designed to reduce benchmark contamination. The TPRM Benchmark rotates task inputs, protects answer keys and uses safeguards to make it harder for models to simply memorize benchmark content.
- Built for statistically rigorous evaluation. Results include confidence intervals and are measured against a baseline so performance reflects meaningful separation rather than one-off gains.
In testing across a wide variety of model configurations, including closed-frontier and open-weight and international models, performance varied significantly by discipline. The TPRM Benchmark assigns each model an autonomy readiness level from L0 to L4 based on repeated-trial performance, helping organizations better understand how to best combine human-machine teams for critical cyber tasks.
Answering questions, such as: where a model may be ready for greater independence and where human oversight is still required.?
Pillar 2: How resilient are models to cyber and supply chain security attacks?
AI agents used in third-party risk workflows may ingest content that vendors or attackers can influence, including questionnaire responses, self-attestations, documents and inbound communications. The TPRM Benchmark tests how models respond to deception, spin and other deliberate manipulation of supply chain security data.
Test attacks on the model itself. The TPRM Benchmark Model Security suite tests models against prompt injection, jailbreak, and other sophisticated attack techniques and grades their resistance from A to F.
- Test attacks embedded in the work. Selected tasks introduce deceptive vendor self-attestations that contradict underlying security telemetry, measuring how much those inputs degrade model accuracy.
“While initial benchmark runs highlight that open weighted models are catching up with leading frontier models across supply chain security tasks, several of those models are highly susceptible to adversarial attacks,” said Mike Mylrea, CISO and Chief AI Officer at SecurityScorecard. “As AI is increasingly deployed for critical security functions, the TPRM Benchmark provides a valuable lens in understanding what models are the best at each task as well as the most trustworthy and resilient.”
That distinction between capability and trustworthiness is also what makes an independent, rigorously designed benchmark so valuable, according to Dr. Yelena Yesha, the Knight Foundation Endowed Chair of Data Science and AI at the Frost Institute for Data Science and Computing (IDSC).
“There are many AI models on the market that deliver the results they promise, but very few adhere to the cybersecurity standards needed for real industry adoption, and that gap is exactly why we need an evaluation platform like this one. I think of a good benchmark like a race track: it shows you which models have real problems under the hood, and it reveals the true limits of what’s possible, which is what makes this work academically meaningful, about scientific discovery, not just about picking the best commercial model off the shelf,” said Dr. Yesha, the Director for the Machine Learning and AI program at IDSC.
“It also matters enormously for organizations trying to use AI in third-party risk workflows specifically. It’s not enough to know a model can complete the task. Done right, a benchmark like this is how you get the confidence to actually deploy AI in these workflows, knowing it does the job well and that its security can be trusted.”
Academic experts say the benchmark’s rigor is what sets it apart. Most organizations deploying AI into supply chain workflows have no way to know whether their chosen model can withstand adversarial attack. They optimize for accuracy, cost, or speed, but rarely for resilience. That’s precisely the problem the TPRM Benchmark was built to solve.
“TPRM Bench stands out by testing AI against real supply chain scenarios grounded in empirical security data,” said Yevgeniy Dodis, Professor of Computer Science at New York University and Fellow of the IACR (International Association for Cryptologic Research). “Its rigorous, reproducible framework helps bridge the gap between benchmark performance and real-world security as AI adoption in critical infrastructure accelerates.”
Industry leaders see the same need for shared, transparent measurement.
“You can’t secure an attack surface you haven’t measured, and TPRM Bench gives security teams a shared, transparent way to evaluate models on capability and attack resistance together,” said Manoj Nair, Chief Technology & Innovation Officer at Snyk. “In our own Snyk research across 3,000 enterprise environments, 74.5% of those with a detected model, reference at least one that scores ‘high’ on an attacker goal under adversarial testing.”
For security leaders, the benchmark also helps decide how much trust to place in AI.
“Preempting the next cyber attack means proving your defenses before they’re put to the test,” said Peter Lee, CEO of SimSpace. “Trust in AI must be earned through continuous testing in realistic, production-like conditions. SecurityScorecard’s TPRM Benchmark helps build that trust by measuring whether AI can perform critical tasks and resist manipulation. For security leaders, validating AI is essential for deciding how much autonomy to give agents and for pinpointing when humans need to remain in control.”
With AI now used by both attackers and defenders, objective measurement matters even more.
“AI is now part of both attacker and defender tooling, so unexpected model behavior can quickly become an incident for one side or an opportunity for the other. At GreyNoise, we’ve seen attackers’ AI use leave identifiable tells, and we’ve seen defenders’ models make mistakes analyzing packets and TTPs,” said Corey Bodzin, Chief Product Officer of GreyNoise. “Objective, transparent measurement like SecurityScorecard’s TPRM AI Benchmark puts evidence of model performance on the table, so defenders can adopt AI with a clear view of its strengths and limits.”
Open Access and Industry Participation
The TPRM Benchmark is open to a select number of AI labs, model providers, security vendors, enterprise security teams, and researchers. Participants can test models and agents against the public benchmark, compare results across capability and attack resistance, and submit results to the open arena.
Get started at https://tprmbenchmark.com/ to download the 2026.09 public release, read the technical report, and register for the arena.
Availability
The TPRM Benchmark public tier, arena access, Model Security suite, and documentation are available today at https://tprmbenchmark.com/
Official expert-verified scores are measured on SecurityScorecard’s live internal tier; public-tier results are directly comparable for research and self-assessment and are labeled as synthetic-calibrated. Enterprises can request a certified evaluation of a candidate model or agent.
Related News:
SecurityScorecard Acquires Driftnet to Expand TITAN AI
Nucleus Security Teams with SecurityScorecard to Enhance Risk and Compliance